minyeamer
Minystory
minyeamer
edit settings
전체 방문자
오늘
어제
  • Category List (97)
    • Books (5)
      • Book Reviews (1)
      • Paper Reviews (4)
    • Life (4)
      • Blog (3)
      • Item Reviews (0)
      • Thoughts (1)
    • Study (34)
      • 2022 (0)
      • AI SCHOOL (34)
      • References (0)
    • Tech (54)
      • Algorithm (46)
      • Projects (6)
      • Python (2)

Blog Menu

  • Home
  • Notice
  • Tags
  • Guest

Popular Posts

Recent Comments

Recent Posts

hELLO
minyeamer

Minystory

[AI SCHOOL 5기] 텍스트 분석 실습 - 텍스트 분석
Study/AI SCHOOL

[AI SCHOOL 5기] 텍스트 분석 실습 - 텍스트 분석

2022. 3. 25. 19:00

1. NLTK Library

  • NLTK(Natural Language Toolkit)은 자연어 처리를 위한 라이브러리
import nltk

nltk.download()

2. 문장을 단어로 토큰화

sentence = 'NLTK is a leading platform for building Python programs to work with human language
data. It provides easy-to-use interfaces to over 50 corpora and lexical resources
such as WordNet, along with a suite of text processing libraries for classification,
tokenization, stemming, tagging, parsing, and semantic reasoning, wrappers for
industrial-strength NLP libraries, and an active discussion forum.'

nltk.word_tokenize(sentence)

Output

['NLTK',
 'is',
 'a',
 'leading',
 'platform',
 ...

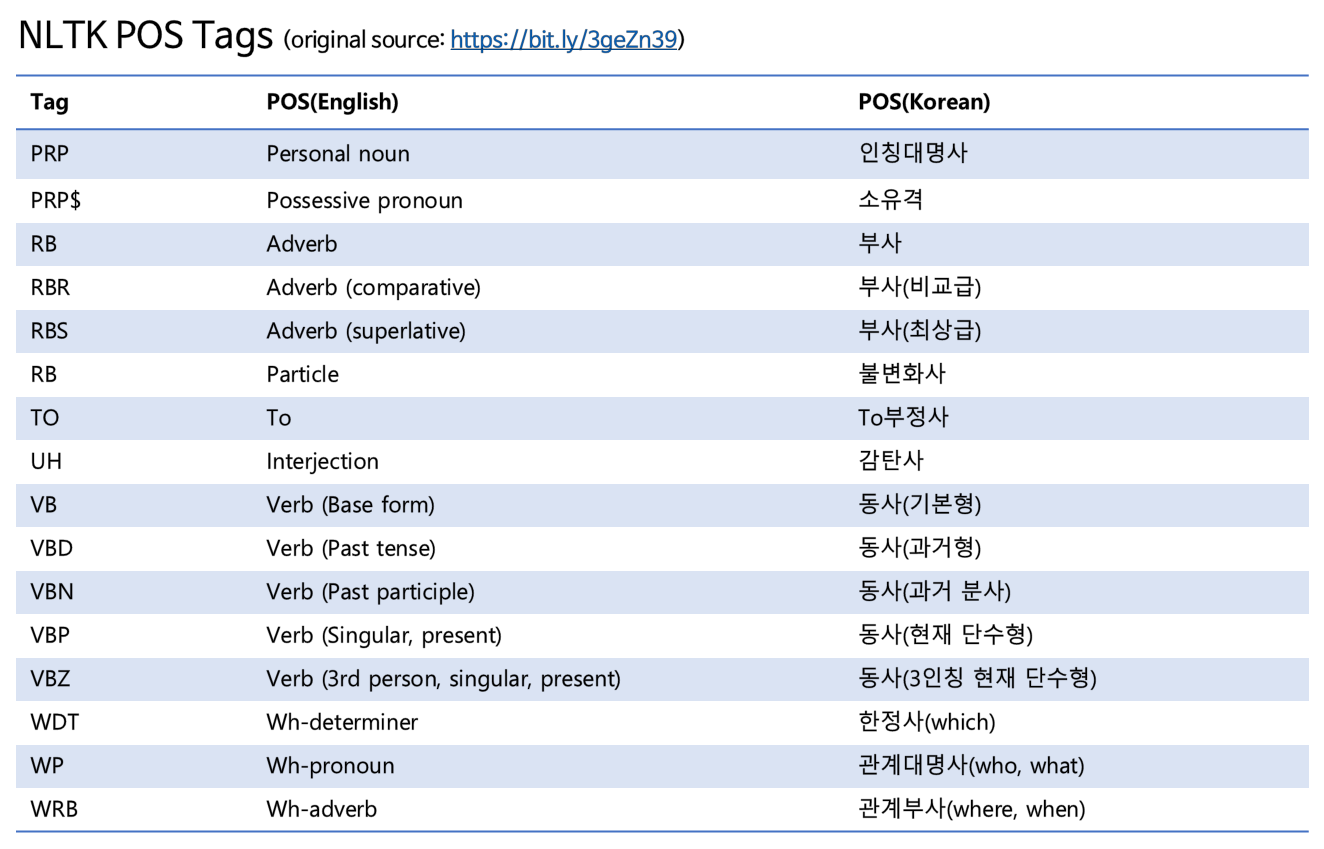
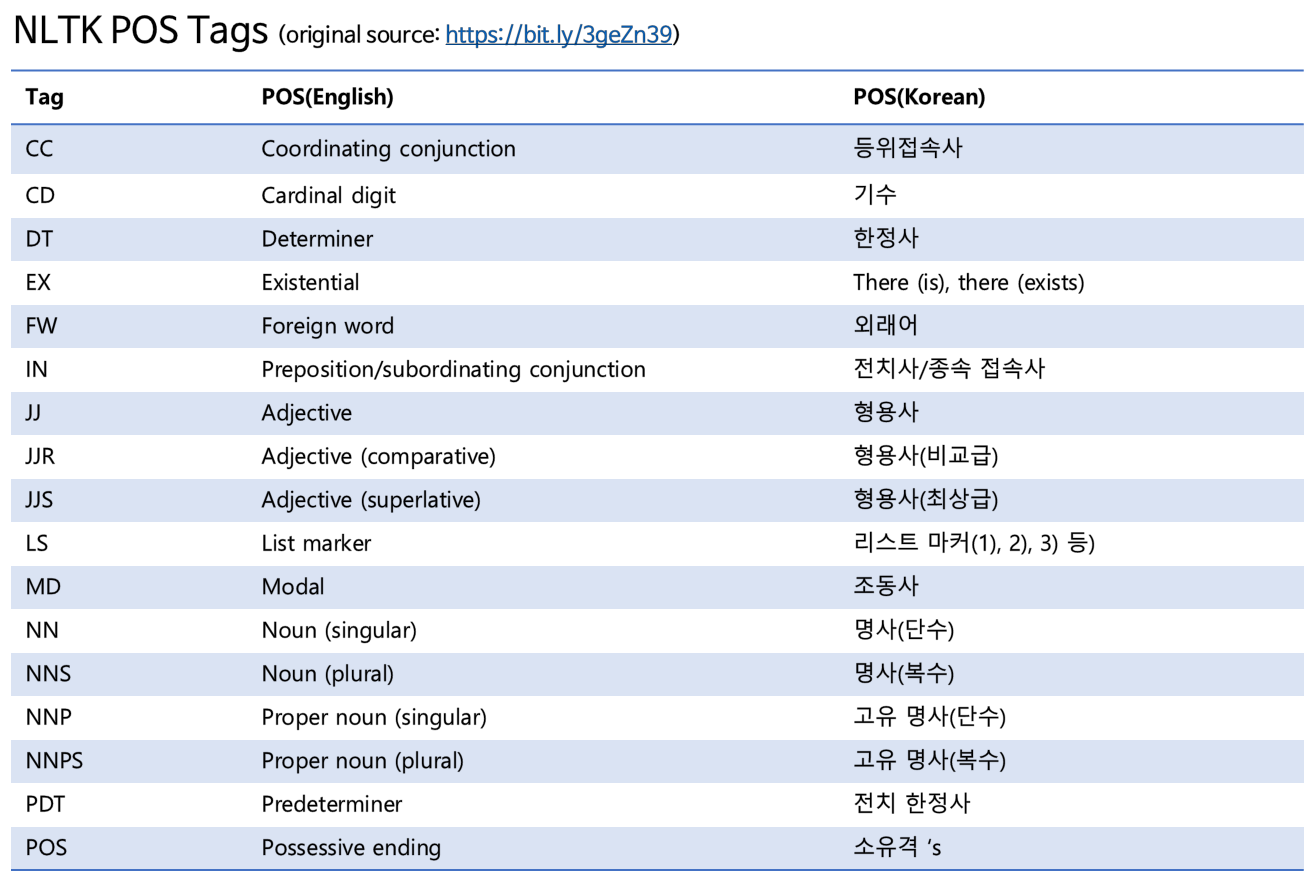
3. POS Tagging

tokens = nltk.word_tokenize(sentence)
nltk.pos_tag(tokens)

Output

[('NLTK', 'NNP'),
 ('is', 'VBZ'),
 ('a', 'DT'),
 ('leading', 'VBG'),
 ('platform', 'NN'),
 ...

NLTK POS Tags List


4. Stopwords 제거

from nltk.corpus import stopwords

stop_words = stopwords.words('english')
stop_words.append(',')
stop_words.append('.')

result = []

for token in tokens:
    if token.lower() not in stopWords:
        result.append(token)

Output

['NLTK', 'leading', 'platform', 'building', 'Python', 'programs', 'work', 'human',
'language', 'data', 'provides', 'easy-to-use', 'interfaces', '50', 'corpora', 'lexical',
'resources', 'WordNet', 'along', 'suite', 'text', 'processing', 'libraries', 'classification',
'tokenization', 'stemming', 'tagging', 'parsing', 'semantic', 'reasoning', 'wrappers',
'industrial-strength', 'NLP', 'libraries', 'active', 'discussion', 'forum']

5. Lemmatizing

  • Lemmatization: 단어의 형태소적/사전적 분석을 통해 파생적 의미를 제거하고,
    어근에 기반하여 기본 사전형인 lemma를 찾는 것
lemmatizer = nltk.wordnet.WordNetLemmatizer()

print(lemmatizer.lemmatize("cats"))             # cat
print(lemmatizer.lemmatize("geese"))            # goose

print(lemmatizer.lemmatize("better"))           # better
print(lemmatizer.lemmatize("better", pos="a"))  # good

print(lemmatizer.lemmatize("ran"))              # ran
print(lemmatizer.lemmatize("ran", 'v'))         # run
  • default로 n 이므로 'cats', 'geese' 들은 기본명사형을 반환
  • 형용사 'better'는 pos에 a를 함께 입력해주어야 원형인 'good'을 반환
  • 동사 'ran'은 pos에 v를 함께 입력해주어야 원형인 'run'을 반환

영화 리뷰 데이터 전처리

file = open('moviereview.txt', 'r', encoding='utf-8')
lines = file.readlines()

sentence = lines[1]
tokens = nltk.word_tokenize(sentence)

lemmas = []
for token in tokens:
    if token.lower() not in stop_words:
        lemmas.append(lemmatizer.lemmatize(token))
저작자표시 (새창열림)

'Study > AI SCHOOL' 카테고리의 다른 글

[AI SCHOOL 5기] 텍스트 분석 실습 - 텍스트 분석  (0) 2022.03.25
[AI SCHOOL 5기] 텍스트 분석 실습 - 텍스트 데이터 분석  (0) 2022.03.25
[AI SCHOOL 5기] 웹 크롤링 실습 - 웹 스크래핑 기본  (0) 2022.03.25
[AI SCHOOL 5기] 웹 크롤링  (0) 2022.03.25
[AI SCHOOL 5기] 데이터 분석 실습 - 데이터 시각화  (0) 2022.03.24
    'Study/AI SCHOOL' 카테고리의 다른 글
    • [AI SCHOOL 5기] 텍스트 분석 실습 - 텍스트 분석
    • [AI SCHOOL 5기] 텍스트 분석 실습 - 텍스트 데이터 분석
    • [AI SCHOOL 5기] 웹 크롤링 실습 - 웹 스크래핑 기본
    • [AI SCHOOL 5기] 웹 크롤링
    minyeamer
    minyeamer
    Better than Yesterday

    티스토리툴바